Agent
FRENZYTableMamba

TableMamba
About this agent
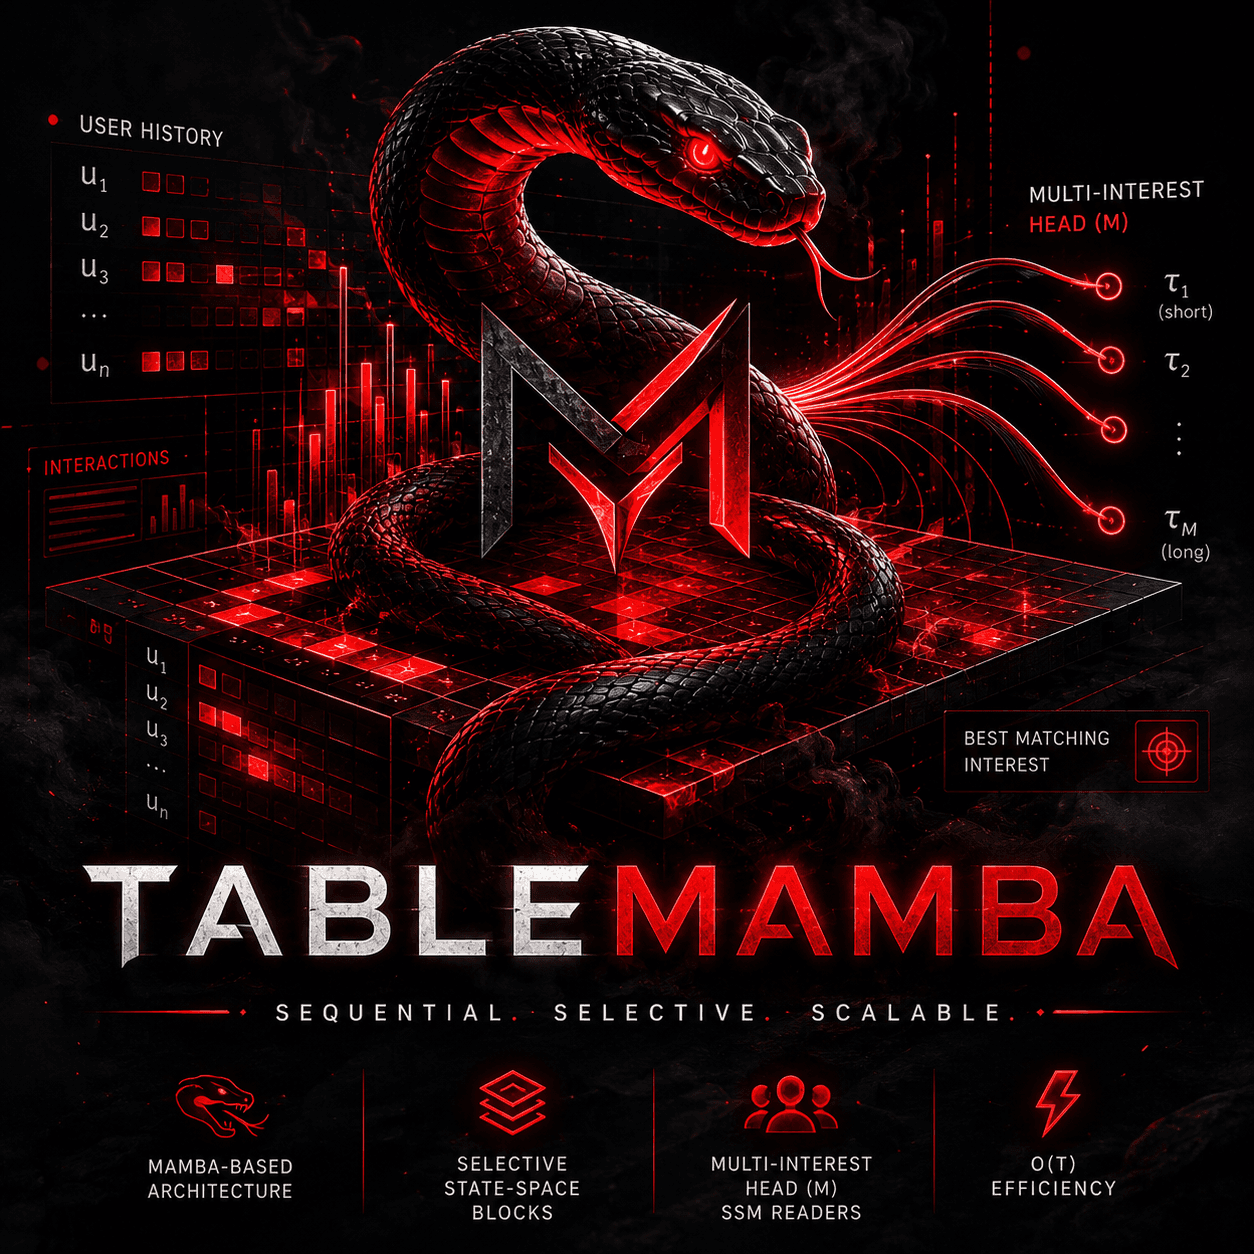
TableMamba is a Mamba-based sequential recommender that encodes a user's interaction history with selective state-space blocks and a multi-interest head of M parallel SSM readers at log-spaced timescales, scoring items by their best-matching interest in O(T).
TableMamba
Implementation of TableMamba, a selective state-space sequential recommender that swaps the attention trunk of a transformer-based ranker for a stack of Mamba blocks, and replaces the single user representation with a multi-interest SSM head that exposes the user as M parallel state-space readers running at log-spaced timescales.
The intuition is simple: a user's history is a long, irregularly-timed stream of interactions whose relevant context spans seconds (the last click) to weeks (long-running preferences). Attention pays an O(T²) cost for the privilege of attending to all of it. A selective SSM compresses the same history into a fixed-size recurrent state at O(T) — and because the state's effective decay is data-dependent, the model can choose to remember the items that actually matter. Multiple heads, each initialized at a different timescale τ_m ∈ [τ_min, τ_max], give us a "short-term interest", "medium-term interest", and "long-term interest" reader for free.
At retrieval time, the user is no longer a single vector — they are M vectors, and an item scores by its best-matching interest:
score(i | user) = max_m u_m · ItemEmbed[i]
Install
$ pip install git+https://github.com/kyegomez/TableMamba.git
The default MambaRec is hand-rolled in pure PyTorch and runs anywhere — CPU, MPS, CUDA. If you have an NVIDIA GPU and want the fast path, install mamba_ssm from source for Mamba3 kernels:
$ MAMBA_FORCE_BUILD=TRUE pip install --no-cache-dir --force-reinstall \
    git+https://github.com/state-spaces/mamba.git --no-build-isolation
Usage
import torch
from table_mamba import MambaRec

model = MambaRec(
    num_items          = 50_000,
    d_model            = 128,
    n_layers           = 4,
    d_state            = 16,
    num_interests      = 4,        # M parallel SSM readers
    max_len            = 200,
    cat_cardinalities  = [100, 50],
    num_numerical      = 2,
)

# left-pad with item_id == 0
item_ids = torch.randint(1, 50_000, (8, 200))
item_ids[:, :20] = 0

# train step
out = model.compute_loss(
    item_ids,
    cat_feats   = torch.randint(0, 100, (8, 200, 2)),
    num_feats   = torch.randn(8, 200, 2),
    time_deltas = torch.rand(8, 200).cumsum(-1),
)
out['loss'].backward()

# retrieval
top_scores, top_items = model.recommend(item_ids, K=10)
Mamba3 backbone
For high-throughput training on CUDA, swap the hand-rolled SSM trunk for mamba_ssm.Mamba3 (about ~100× faster on long sequences via the fused selective scan kernel):
from table_mamba import Mamba3Rec

model = Mamba3Rec(
    num_items     = 50_000,
    d_model       = 128,
    n_layers      = 4,
    num_interests = 4,
    dtype         = torch.bfloat16,
).cuda()
Mamba3Rec keeps the same multi-interest contract and loss; the trunk runs MIMO Mamba3 blocks and each interest head is its own SISO Mamba3 block with per-head A_log offsets to enforce distinct timescales at initialization.
How it works
       item_ids ─┐
   cat_feats ────┤
   num_feats ────┼──► InteractionEmbed ──► (B, T, d_model)
   time_deltas ──┤        (item + cat + num + pos + log-time, pad-zeroed)
       ──────────┘
                              │
                              ▼
                ┌──────────────────────────┐
                │  (L-1) × MambaBlock      │   trunk
                │   RMSNorm                │   ─ shared front-end:
                │   in_proj → (a, z)       │       norm → in_proj → conv1d → SiLU
                │   causal conv1d (d_conv) │   ─ selective SSM:
                │   SelectiveSSM(A,B,C,Δ)  │       Δ, B, C input-dependent
                │   gate(SiLU(z))          │       A = -exp(A_log), diagonal
                │   out_proj + residual    │       y = Σ_t (h_t ⊙ C_t) + D⊙x
                └──────────────────────────┘
                              │
                              ▼
                ┌──────────────────────────┐
                │  MultiInterestSSMHead    │   head — M parallel SSMs
                │   shared front-end       │     share norm / in_proj / conv / z
                │   M × {A_m, B_m, C_m,    │     differ in A,B,C,Δ → distinct
                │        Δ_m, out_proj_m}  │     timescales τ_m ∈ [τ_min, τ_max]
                │   head_norm (shared)     │
                └──────────────────────────┘
                              │
                              ▼
                       (B, T, M, d_model)
                              │
        score(i) = max_m  u_m · ItemEmbed[i]
Selective SSM. Each block runs the S6 / Mamba selective scan: x_proj produces input-dependent (Δ, B, C) per token, A = -exp(A_log) is a learned diagonal decay, and the state is discretized as Ā = exp(Δ ⊙ A), B̄x = Δ ⊙ B ⊙ x. The recurrence h_t = Ā_t h_{t-1} + B̄x_t, y_t = (h_t ⊙ C_t).sum(-1) + D ⊙ x_t runs in O(T) with a fixed-size hidden state.
Multi-interest head. The final layer replaces the single SSM with M SSMs sharing one front-end (norm / in_proj / depthwise conv / z-gate) but with distinct (A_m, B_m, C_m, Δ_m, out_proj_m). A_log offsets are log-spaced so head m is born at timescale τ_m = τ_min · (τ_max / τ_min)^{m/(M-1)}. The trunk residual is not added back at the head — that would re-merge the interest streams.
Training. Dense next-item prediction with hard-routed sampled softmax: for each (B, T) position we pick the head whose vector best matches the true next item, and the cross-entropy is computed only on that winning head. This is regularized with:
- a diversity loss — mean squared off-diagonal cosine between per-user head vectors, pushing the
Minterests apart; - a load-balancing loss —
M · Σ p_m² − 1, minimized at uniform head usage, preventing one head from absorbing everything.
Inference. At the most-recent position, score every item once per head and take the max. Production deployments can swap the dense scoring for a per-head ANN lookup with union — each head queries its own posting list, results are merged.
Padding convention
Sequences are left-padded with padding_idx (default 0) so that position -1 is always the most recent interaction. Pad rows are zeroed out after embedding so the selective scan truly sees zeros there (and Mamba ops preserve zeros — B̄x = Δ ⊙ B ⊙ 0 = 0, so the hidden state simply carries through).
Citations
@inproceedings{Gu2023MambaLS,
    title   = {Mamba: Linear-Time Sequence Modeling with Selective State Spaces},
    author  = {Albert Gu and Tri Dao},
    year    = {2023},
    url     = {https://arxiv.org/abs/2312.00752}
}
@inproceedings{Dao2024TransformersAS,
    title   = {Transformers are SSMs: Generalized Models and Efficient Algorithms Through Structured State Space Duality},
    author  = {Tri Dao and Albert Gu},
    year    = {2024},
    url     = {https://arxiv.org/abs/2405.21060}
}
@inproceedings{Gu2022EfficientlyML,
    title   = {Efficiently Modeling Long Sequences with Structured State Spaces},
    author  = {Albert Gu and Karan Goel and Christopher R{\'e}},
    year    = {2022},
    url     = {https://arxiv.org/abs/2111.00396}
}
@inproceedings{Kang2018SelfAttentiveSR,
    title   = {Self-Attentive Sequential Recommendation},
    author  = {Wang-Cheng Kang and Julian McAuley},
    year    = {2018},
    url     = {https://arxiv.org/abs/1808.09781}
}
@inproceedings{Cen2020ControllableMR,
    title   = {Controllable Multi-Interest Framework for Recommendation},
    author  = {Yukuo Cen and Jianwei Zhang and Xu Zou and Chang Zhou and Hongxia Yang and Jie Tang},
    year    = {2020},
    url     = {https://arxiv.org/abs/2005.09347}
}
@inproceedings{Li2019MultiInterestNN,
    title   = {Multi-Interest Network with Dynamic Routing for Recommendation at Tmall},
    author  = {Chao Li and Zhiyuan Liu and Mengmeng Wu and Yuchi Xu and Pipei Huang and Huan Zhao and Guoliang Kang and Qiwei Chen and Wei Li and Dik Lun Lee},
    year    = {2019},
    url     = {https://arxiv.org/abs/1904.08030}
}
@misc{Gomez2025TableMamba,
    title        = {TableMamba: Selective State-Space Sequential Recommendation with Multi-Interest Readers},
    author       = {Kye Gomez},
    year         = {2025},
    publisher    = {GitHub},
    journal      = {GitHub repository},
    howpublished = {\url{https://github.com/kyegomez/TableMamba}}
}
License
Apache 2.0
Requirements
| Package | Installation |
|---|---|
| requests | pip3 install requests |
Agent Code
The main implementation code for this agent
Chart
Loading chart...
Comments & Discussion
Scroll to load comments...
Tags
Share


Loading recommendations...